
Jev Search: Open Source AI Search Engine, Achieving Intent Parsing and Multi-Engine Aggregation Based on the Jev Model
Executive Summary:
Jev Search is an open-source AI search engine frontend developed by the Search1API team. Its core functionality lies in leveraging the Jev structured decision model introduced by the TypeSafe team, en...
1. What is Jev Search
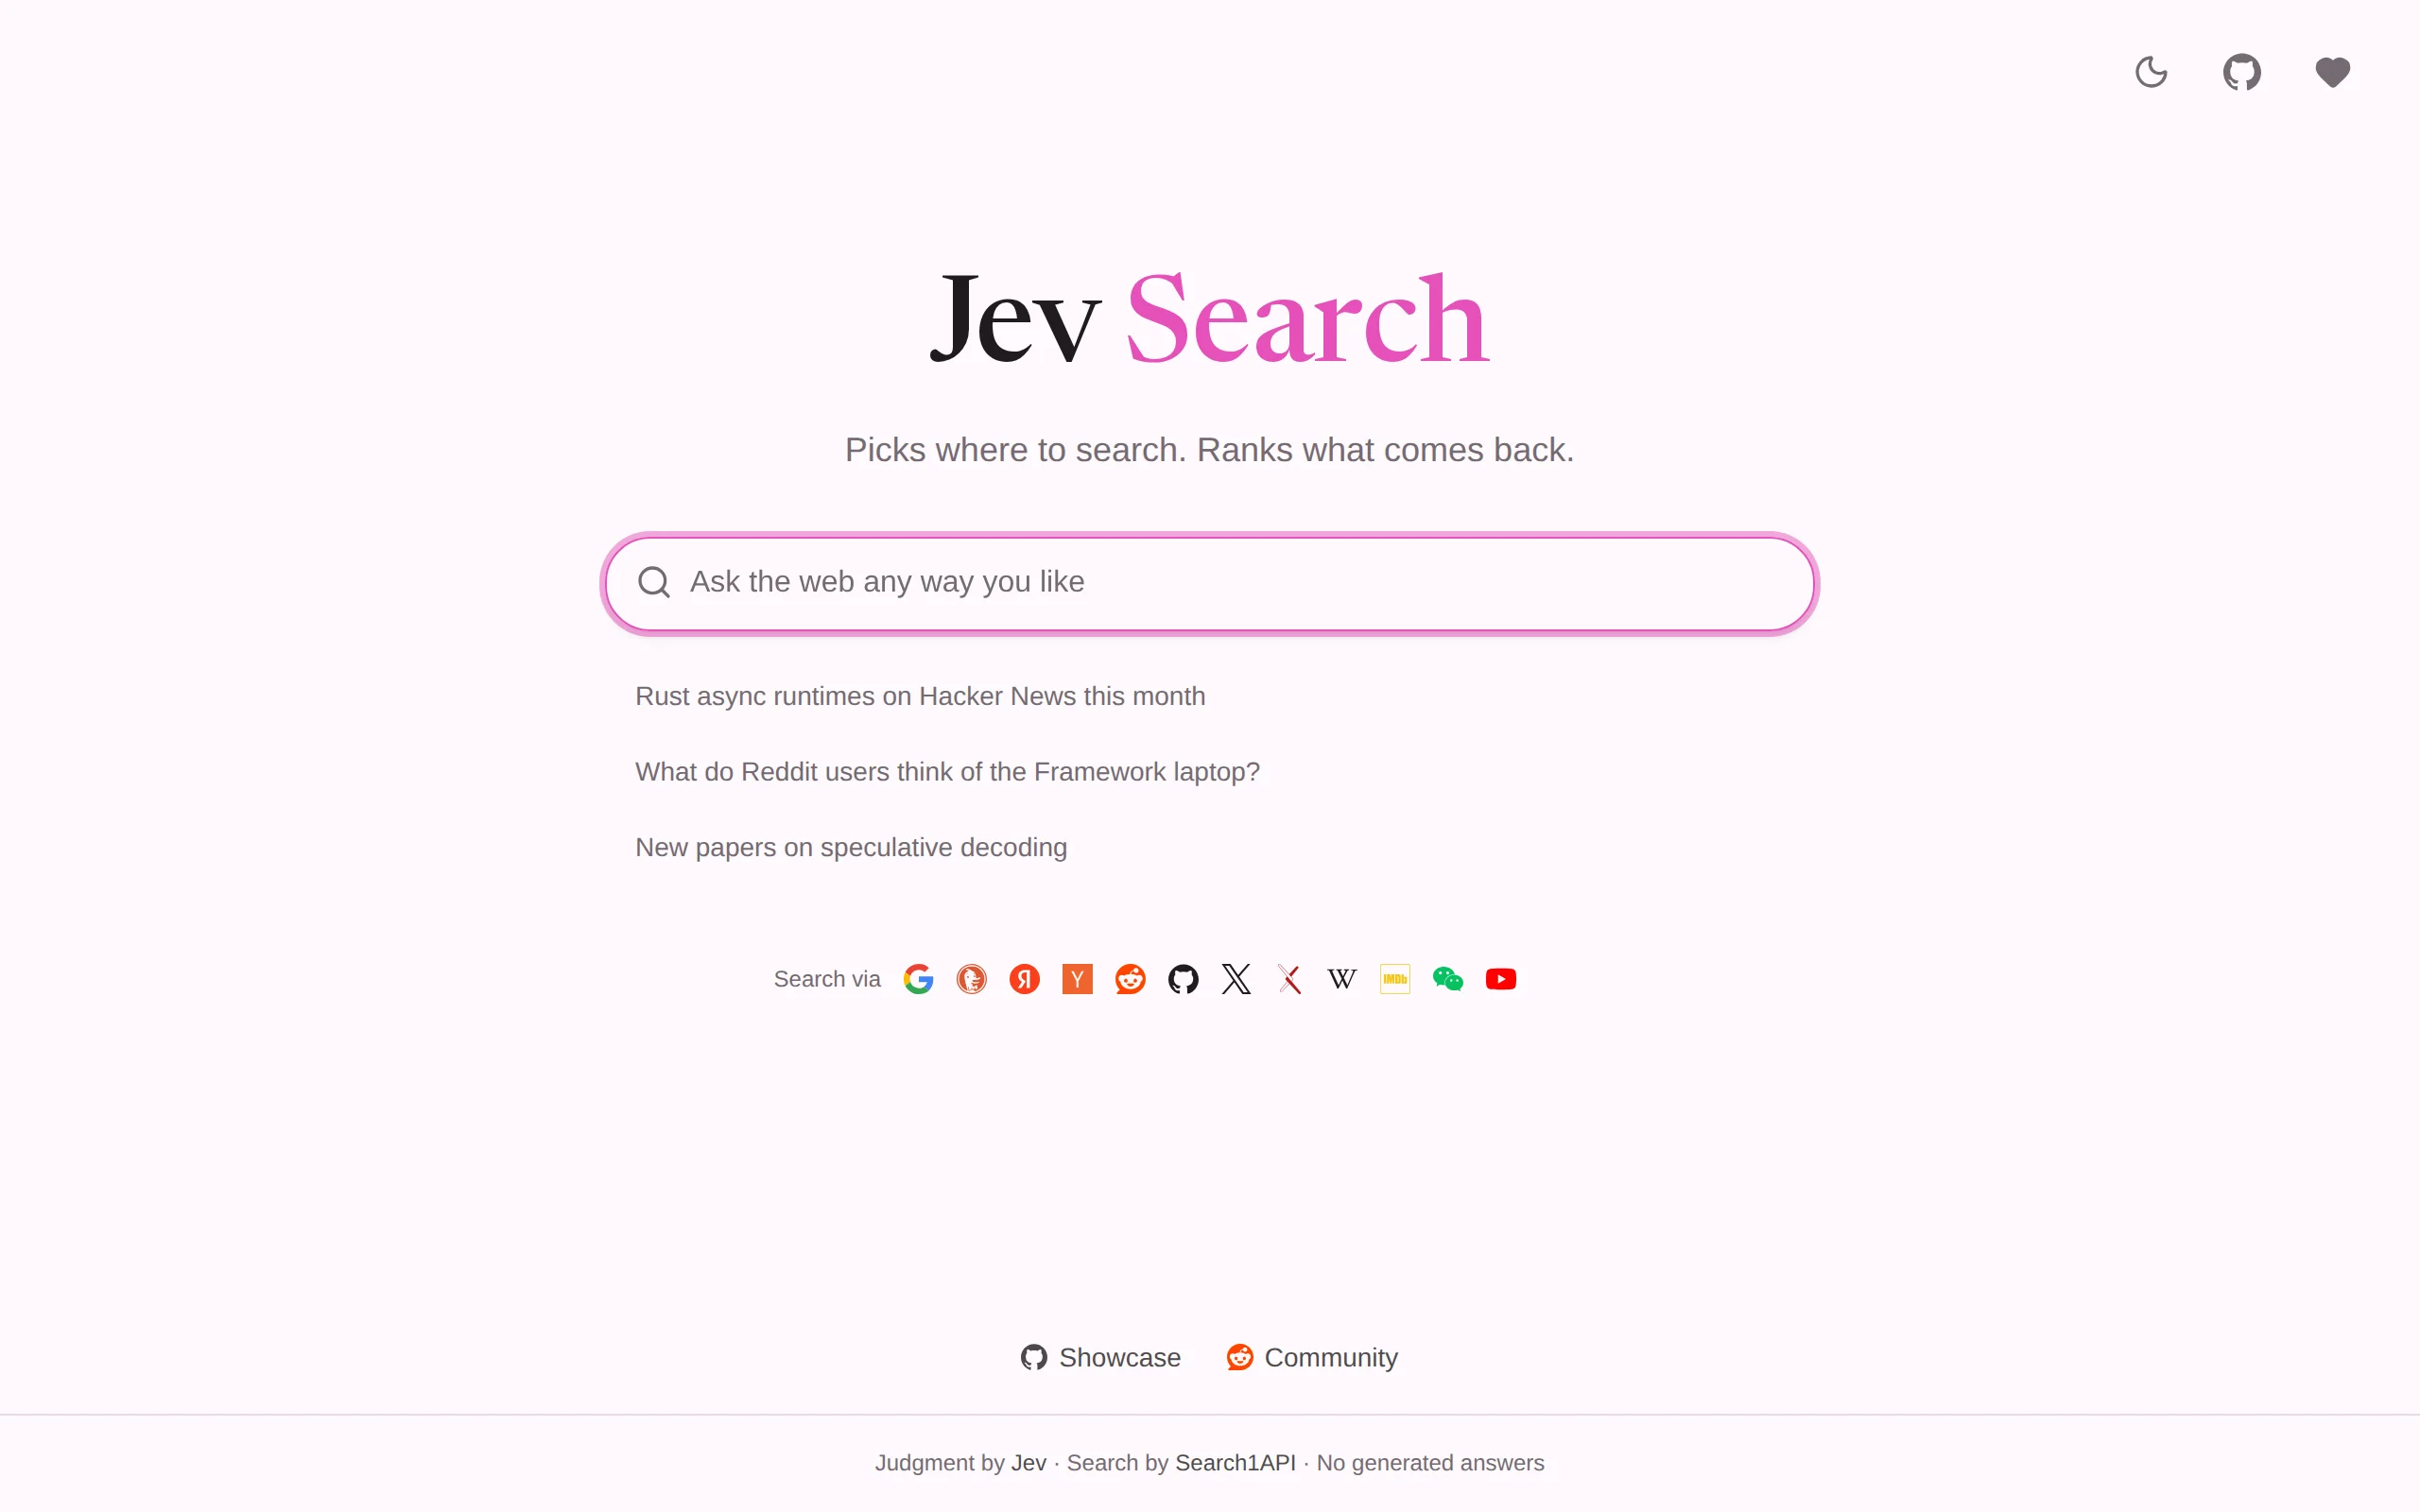
Jev Search is an open-source AI search engine frontend developed by the Search1API team. Its core functionality lies in leveraging the Jev structured decision model introduced by the TypeSafe team, enabling intent parsing of user natural language queries, selection of search sources, time range constraints, and automatic query term generation. After the Jev model completes the query planning, the system concurrently invokes 12 search and content engines, including Google, Reddit, Hacker News, and arXiv, via Search1API. Each returned result is assigned a relevance score ranging from 0 to 100 and displayed incrementally in a streaming fashion, with low-scoring results automatically grouped into a separate category.
Image source: Official article
Image source: official article
Technical positioning and domain: This project falls within the intersection of natural language processing and information retrieval. It is positioned as an open-source, self-hostable AI search aggregation frontend, distinguishing itself from commercial closed-source products like Perplexity. Its core innovation lies in shifting the role of the LLM from "generating answers" to "planning queries and evaluating results," thereby addressing hallucinations and omissions in generative AI from an architectural standpoint.
Development background: The project was developed by the Search1API team, which has long focused on building a unified API aggregation layer and possesses the capability to integrate channels covering mainstream search engines and vertical community content. The Jev model was introduced by TypeSafe, specializing in structured multi-step decision-making and logical reasoning. The combination of these two enables efficient collaboration within a unified system for understanding search intent and multi-source scheduling.
Core value: Targeting two major pain points of traditional AI search—generative answers may fabricate facts and users have difficulty participating in the retrieval process—Jev Search provides a clear design solution: the system only returns source links and summaries, without AI-generated summaries. Additionally, the Jev model's judgment logic is transparently presented in the form of tags, allowing users to manually adjust sources, time ranges, and query terms. This "find the answer, not provide the answer" positioning gives it unique value in scenarios requiring high accuracy in information, such as academic tracking, technical research, and sentiment analysis.
Technical features: Using the intent parsing capabilities of the Jev model as the central query planning component, combined with the parallel scheduling architecture of Search1API's 12 engines, it delivers a broad coverage and low-latency search experience. Each result is accompanied by an interpretable relevance score, with the sorting logic fully transparent; streaming output is paired with edge deployment strategies to ensure fast global response times; the code is open-sourced under the MIT license and supports deployment on Cloudflare Workers for data control.
2. Key Features
Natural Language Search: Users do not need to extract keywords or design search syntax; they can initiate a search by simply describing their needs in everyday spoken language. The Jev model is responsible for converting colloquial expressions into structured query parameters, significantly lowering the search barrier, especially for ordinary users unfamiliar with advanced search commands.
Intent Understanding and Query Planning: The Jev model automatically analyzes the deeper needs behind user questions, identifying the search topic, source scope (e.g., Reddit, arXiv), and time range (e.g., past week, past month), and generates specific search terms. This capability condenses multiple manual steps traditionally required in search into a single question, significantly shortening the distance from demand to results.
Parallel Multi-Engine Scheduling: The system uniformly calls 12 search and content engines, including Google, Reddit, Hacker News, and arXiv, via the Search1API. All requests are sent in parallel. A failure or timeout in a single engine does not affect the overall result display. This redundant architecture enhances the reliability and breadth of search tasks, covering general web pages, community discussions, and specialized academic content.
Relevance Scoring and Transparent Ranking: Jev Search calculates a relevance score for each search result, ranging from 0 to 100, and directly displays it next to the result link. Unlike most search engines that treat ranking logic as a black box, this transparent scoring mechanism allows users to clearly understand the rationale behind each result's recommendation and make their own judgments about the ranking's validity.
Streaming Result Display: Search results are displayed one by one in the order they are returned by the engines. Earlier results are shown first, without requiring all 12 engines to complete their responses. Combined with the edge deployment of Cloudflare Workers, this streaming architecture significantly reduces the time it takes for users to see the first set of results, enhancing the immediacy and smoothness of the interaction.
Manual Override and Fine-Grained Control: Users can directly add or remove source tags, modify the time range, edit the search terms, and immediately re-run the search on the results page. This design returns control of the search process to the user, allowing the system to leverage AI for query planning while still maintaining the flexibility of manual intervention, balancing efficiency with controllability.
Only Returns Links and Summaries: The system deliberately avoids AI-generated summaries and only displays source links and summary information. This design choice fundamentally prevents issues such as fabricated content or the omission of key information that can occur when generative models aggregate information, ensuring the traceability of returned content. It is well-suited for research scenarios with high requirements for information authenticity.
Open Source and Self-Hosted: The project is open-sourced on GitHub under the MIT license. Users can clone the repository, configure their own Search1API and Jev API Key, and deploy the complete search engine to their own Cloudflare Workers environment. In self-hosted mode, search data is controlled by the user, independent of third-party hosting, meeting data privacy and compliance requirements.
3. How to Use
Environment Requirements: Jev Search offers two deployment options: hosted and self-hosted. The hosted version requires no installation and can be accessed directly on any device with a modern browser. For self-hosted deployment, you need a GitHub account, a Cloudflare Workers environment, and valid API Keys for Search1API and the Jev model. Basic knowledge of JavaScript and edge function deployment is recommended.
Access the Website: Simply visit the Jev Search official website via your browser at https://jev.s1.dev/ to enter the search interface. The site supports PWA features, allowing users to install it as a desktop or mobile application through the browser menu's "Add to Home Screen / Add to Desktop" option, providing a native app-like experience.
Input Questions and Initiate Search: Describe your needs in natural language directly in the search box, without the need for keyword extraction or syntax conversion. For example, entering "Rust async runtimes on Hacker News this month" will automatically be parsed by the Jev model to identify the intent: the search topic is Rust asynchronous runtimes, the source is limited to Hacker News, and the time range is this month.
Review and Adjust Jev's Interpretation: Before displaying the search results, the system will show the source selection, time range, and query terms generated by the Jev model as tags on the page. If users believe there are inaccuracies in the interpretation, they can directly click the tags to add, remove, or modify them, then re-run the search to ensure the query aligns with their actual needs.
Browse Streaming Results: Search results are displayed sequentially on the page as they are returned by the engines. Each link is accompanied by a relevance score ranging from 0 to 100. Users can begin preliminary filtering and clicking on the results without waiting for all engines to complete their responses.
View Low-Score Results Group: Links with lower relevance scores are automatically grouped into a separate "Low-Score Results" section, which is collapsed by default. Users can expand this section as needed to view content deemed to have low relevance by the system, preserving a channel for exploring edge information.
Self-Hosted Deployment (Optional): Clone the repository from GitHub (https://github.com/superagents-lab/jev-search), configure the environment variables according to the README instructions, input the Search1API and Jev API Keys, and deploy the project to Cloudflare Workers. Once deployed, you will have a fully autonomous private AI search engine instance.
4. Pros and Cons Analysis
| Pros |
|---|
| Eliminates hallucination generation: The system only returns links and summaries, without generating AI summaries. This architectural choice avoids issues where generative models fabricate content or omit key information, ensuring that every piece of information can be traced back to its original source. |
| Automated search intent processing: The Jev model automatically converts colloquial questions into precise search terms, source ranges, and time constraints, eliminating the need for users to manually refine keywords or set filters. This significantly lowers the barrier to entry for searching. |
| Transparent and controllable ranking logic: Each result is accompanied by a relevance score ranging from 0 to 100. The source, time, and query terms can be directly modified on the page. Users can clearly see the ranking criteria and intervene at any time, making the search process fully explainable. |
| Multi-engine broad coverage and fault tolerance: A single query schedules 12 engines in parallel, covering content sources such as general web pages, community discussions, academic papers, and WeChat official accounts. A failure in a single engine does not affect the overall quality and completeness of the results. |
| Open source and self-hostable with data control: Open-sourced under the MIT license, users can deploy the full search engine on Cloudflare Workers. Search behavior and data are entirely under personal control, without going through third-party platforms, meeting data privacy requirements. |
5. Comparative Analysis with Similar Tools
| Comparison Dimension | Jev Search | Perplexity | Phind |
|---|---|---|---|
| Product Form | Open-source AI search frontend, MIT license, can be self-hosted on Cloudflare Workers | Commercial closed-source AI search product, offering Web and API services | AI search engine for developers, commercial closed-source |
| Result Format | Returns only source links + summaries, does not generate AI summaries, avoids hallucinations and information loss | Generates summary-style answers with reference links, balancing quick browsing and source tracing | Generates technical answers with code examples and source links, focusing on developer scenarios |
| Sorting Mechanism and Transparency | Jev model assigns a relevance score of 0-100 to each result, with the score displayed directly, and the sorting basis is transparent | Internal sorting algorithm, users cannot see the scoring rationale, sorting logic is opaque | Internal relevance sorting, combined with real-time web indexing, but the sorting reasons are not explained to users |
| Controllability and Intervention Ability | Users can manually modify source tags, time ranges, and query terms, allowing full intervention in the search process | Can limit search scope using the Focus feature, but the specific query process is not controllable | Supports advanced filters and time limits, but the query parsing process is not open to users |
| Search Coverage | Parallel scheduling of 12 engines, including Google, Reddit, Hacker News, arXiv, WeChat Official Accounts, etc., with strong coverage of community and niche content | Self-built index + partner data sources, strong general web coverage, relatively weaker community content coverage | Primarily web index and technical communities like Stack Overflow, with limited general content coverage |
| Deployment Method | Supports self-hosted deployment, can run on Cloudflare Workers, with full data control | Only offers official hosted services, users cannot self-deploy | Only offers official hosted services, no self-hosting option |
| Open Source License and Community Ecosystem | MIT license, fully open-source code, developers can freely modify and redistribute | Closed-source, no community ecosystem, relies on official updates | Closed-source, no community expansion mechanism |
Selection Recommendations: For research-oriented users and developer communities, Jev Search's transparent sorting mechanism and fully controllable search process offer unique advantages in scenarios requiring verification of information sources and precise control over search scope; its self-hosting capability also provides a viable solution for teams with strict data privacy requirements. Perplexity offers a more direct experience in consumer-level scenarios where quick access to summary answers is needed, making it suitable for users who prioritize speed of information retrieval over depth of source verification. Phind specializes in technical development Q&A, making it a more precise choice for developers needing to resolve specific coding issues, although its coverage breadth is far less than Jev Search's parallel 12-engine architecture. Kagi targets advanced users willing to pay for independent indexing and privacy protection, achieving a good balance between control and coverage, but lacks the flexibility of open-source self-hosting.
6. Editor's Summary
Jev Search has made a notable architectural trade-off in its product design for an AI search engine: abandoning generative summaries and instead focusing the large language model's capabilities on query planning and result evaluation. This design choice directly addresses two inherent flaws of generative AI search—hallucinations and information omission—by outputting a fully traceable list of links, ensuring that every piece of information provided to the user has a clear original source. In terms of controllability of retrieval quality, Jev Search publicly displays sorting criteria in a 0 to 100 rating format and provides manual override capabilities for sources, time, and query terms. This stands out as a differentiating advantage in the current landscape where most AI search products treat sorting logic as a black box.
In terms of practical value, this tool can play a substantive role in scenarios requiring multi-source cross-verification, such as technical research, academic tracking, and product reputation analysis. The combination of parallel scheduling across 12 engines and streaming display achieves a good balance between response speed and information breadth. In terms of target users, Jev Search is more suitable for researchers, developers, and self-hosting enthusiasts who prioritize the accuracy of information sources, rather than general consumer users seeking quick, summarized answers. The project is open-sourced under the MIT license, allowing for free modification and redistribution, which preserves space for the community to expand vertical features on its foundation (such as adding more search engine integrations or developing front-end plugins). In the future, if it can further iterate on multi-turn conversational retrieval and result deduplication and aggregation, its position within the AI search tool ecosystem will become even more solid.
7. Application Scenarios
Developer Technical Research: Developers can use natural language to search for community discussions on specific technical topics, such as retrieving real user reviews about "Rust async runtimes" from Hacker News. The Jev model automatically identifies the source and time range, aggregating fragmented practical experiences and performance feedback from the community. This helps developers reference real user insights rather than one-way promotions from official documentation when choosing frameworks.
Academic Paper Tracking: Researchers can input questions like "New papers on speculative decoding," and Jev Search automatically restricts the source to arXiv and sets an appropriate time range, enabling continuous tracking of the latest research findings in specific fields. The streaming display mechanism ensures newly published papers are shown immediately, significantly reducing the waiting time for manual polling across various academic databases.
Product Reputation and User Feedback Analysis: Product managers and market researchers can directly ask questions such as "What do Reddit users think of the Framework laptop?" The system performs parallel searches across multiple communities like Reddit and Hacker News, aggregating multi-faceted user evaluations of the product. By reviewing relevance scores and low-score groups, researchers can quickly identify representative feedback and niche opinions.
Competitor and Market Dynamics Monitoring: Market analysts can search for industry keywords within a specific time frame, leveraging the system's multi-engine parallelism and streaming display capabilities to simultaneously obtain the latest updates from news media, social platforms, and specialized information sites. The low-score result grouping mechanism helps capture emerging trends that have not yet been widely reported by mainstream media, providing early signals for competitive strategy development.
Multi-Perspective Verification of Hot Events: When dealing with sudden events or controversial topics, users can obtain multi-source information through a single query, including news websites, social platforms, and academic databases. The system compares different sources' perspectives and timelines, helping users identify potential biases or information gaps in single sources and forming a more comprehensive basis for judgment.
8. FAQ
Q: What is the core difference between Jev Search and Perplexity?
A: The core difference lies in the form of results and the transparency of ranking. Jev Search only returns links and summaries, without generating AI summaries, thereby fundamentally avoiding issues of hallucination and information omission inherent in generative models. In contrast, Perplexity generates comprehensive summary-style answers. Additionally, Jev Search directly displays relevance scores (0-100) for each result to the user, and allows manual modification of sources, time, and query terms, making the search logic fully transparent. Perplexity does not disclose its ranking criteria to users, offering limited opportunities for intervention.
Q: Is Jev Search free to use? Are there costs associated with self-hosted deployment?
A: The hosted version of the service is free to access and use. For self-hosted deployment, the project code is fully open-source under the MIT license, with no licensing fees. However, users must bear the API call costs for Search1API and the Jev model, as well as the resource consumption costs of Cloudflare Workers. Specific costs depend on the actual query volume, and for low usage, self-hosting costs are manageable.
Q: Why does Jev Search not generate AI summaries and only return links and summaries?
A: This is a deliberate design choice. Generative AI faces two inherent risks during information aggregation: one is the potential fabrication of content not present in the original text (hallucination), and the other is the possible omission of key information. Jev Search opts to return only traceable links and summaries, ensuring that each piece of information can be verified, allowing users to read the original content and make their own judgments. This design sacrifices some convenience in quickly scanning information, but in exchange, it offers higher information reliability.
Q: What technical preparations are required for self-hosted deployment of Jev Search?
A: You will need a GitHub account to clone the repository, a Cloudflare Workers environment for deployment, and a valid API Key for Search1API and the Jev model. The deployment process involves configuring environment variables and publishing edge functions, and it is recommended that users have basic JavaScript knowledge and experience with deploying on edge computing platforms. The project README provides deployment steps, but overall, it is more suitable for users with a development background.
Q: Is the relevance score of Jev Search absolutely accurate?
A: The relevance score is calculated by the Jev model based on the semantic match between the query intent and the result content. It is a model's judgment rather than an absolute objective standard. Since users' actual needs may go beyond the literal meaning of the query terms, there may be some deviation in the scores. The system provides a manual override mechanism: users can modify the query terms, sources, and time ranges and re-search, or they can directly ignore the scores and look for potentially valuable content in lower-scoring groups.
Q: Does Jev Search support Chinese searches?
A: The Jev model has natural language understanding capabilities in multiple languages, allowing users to directly ask questions in Chinese. The system can normally parse the intent and generate query terms. In terms of search coverage, among the 12 engines scheduled by Search1API, several include Chinese content sources such as WeChat Official Accounts, thus providing good coverage for Chinese content. For community discussion needs in pure Chinese, it is recommended to explicitly specify the source in the query to obtain more accurate results.
9. Project Links
- Product Website: https://jev.s1.dev/
- GitHub Repository: https://github.com/superagents-lab/jev-search
Related AI Model Articles
Ok Work – Baidu's AI On-the-Go Office Tool
Ok Work is Baidu's lightweight AI on-the-go office tool, running in the form of a WeChat Mini Program, targeting students and new professionals, and focusing on fragmented office scenarios. The produc...
WebCraftBench – A Benchmark for AI Web Page Generation Introduced by Tencent in Collaboration with Tsinghua University
WebCraftBench is a benchmark for evaluating the quality of AI-generated web applications, introduced jointly by Tencent HunYuan, Tsinghua University, and Peking University. It aims to address the indu...
Xiaomi-CocktailASR-1: In-Depth Evaluation of a Target Speaker ASR Model Based on an End-to-End LLM Architecture
Xiaomi-CocktailASR-1 is Xiaomi's open-source Target Speaker ASR (TS-ASR) large model, designed using an end-to-end LLM architecture. It uses a reference speech as a speaker embedding prompt to accurat...
Deep Dive into RAG (Retrieval Augmented Generation) for Large Models: From Basic Workflows to Advanced Retrieval Architectures and Optimization
I want to explain RAG (Retrieval Augmented Generation) from the basics to advanced concepts, as it has become one of the most popular solutions for deploying large models in real-world applications. I
© All Rights Reserved. Some content on this site is partially generated by AI with human review.